How the pieces connect
A visual, redacted map of the local language, image, prompt-engineering, and web layers behind The Side Quest Lab.
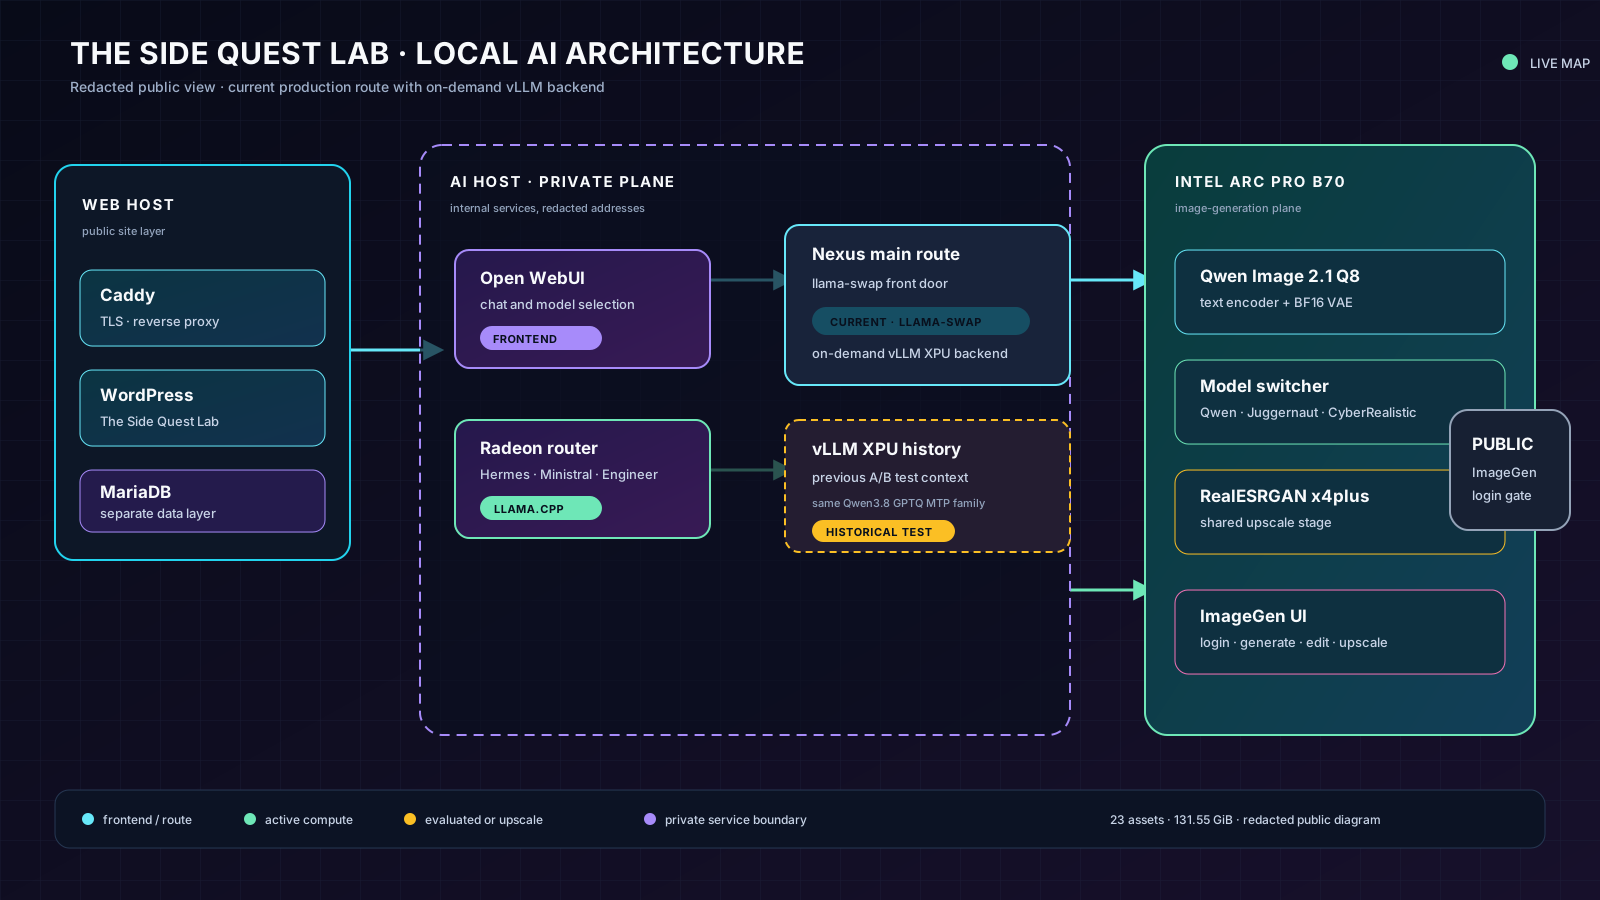
Live status: 21 September 2026, 23:09 IST. This document describes the local AI infrastructure as it was live on the AI host and web host. Written by Sirius.
Security boundary. This documentation contains architecture, model names, file categories, internal service roles, and official download pages. Passwords, API keys, SSH keys, session cookies, database passwords, and other credential values are intentionally excluded. Internal addresses are intended only for the trusted LAN or VPN.
At a glance
Our local AI environment runs primarily on the AI host ([internal AI host]). The AI host provides the local language models, the Open WebUI chat environment, and the Intel Arc image-generation stack. The web host (web-host) hosts this WordPress site and its database behind Caddy, among other services.
- 23 model and image assets on the AI host.
- 141,250,127,635 bytes, approximately 131.55 GiB.
- Radeon Vulkan: local language models and the prompt rewriter.
- Intel Arc Pro B70: Qwen Image, the image switcher, Juggernaut XL, CyberRealistic, and upscaling.
- Web host: WordPress, MariaDB, Caddy, and the other web-host services.
Important environment links
- The Side Quest Lab, the canonical public WordPress site.
- WordPress administration, protected by the existing login.
- Local ImageGen environment, publicly reachable behind the ImageGen login. The route redirects to
/imagineer/login. internal Open WebUI chat environment, Open WebUI on the trusted LAN.internal main model route, the internal OpenAI-compatible main model route.internal Radeon model route, the internal Radeon model route.fixed Arc image service, the fixed ComfyUI Qwen Image service.Arc image switcher, the ComfyUI image-model switcher.
DNS note: the public documentation route uses the canonical URL https://thesidequestlab.com. Internal chat and image services are intentionally described by function rather than published with their real addresses or ports.
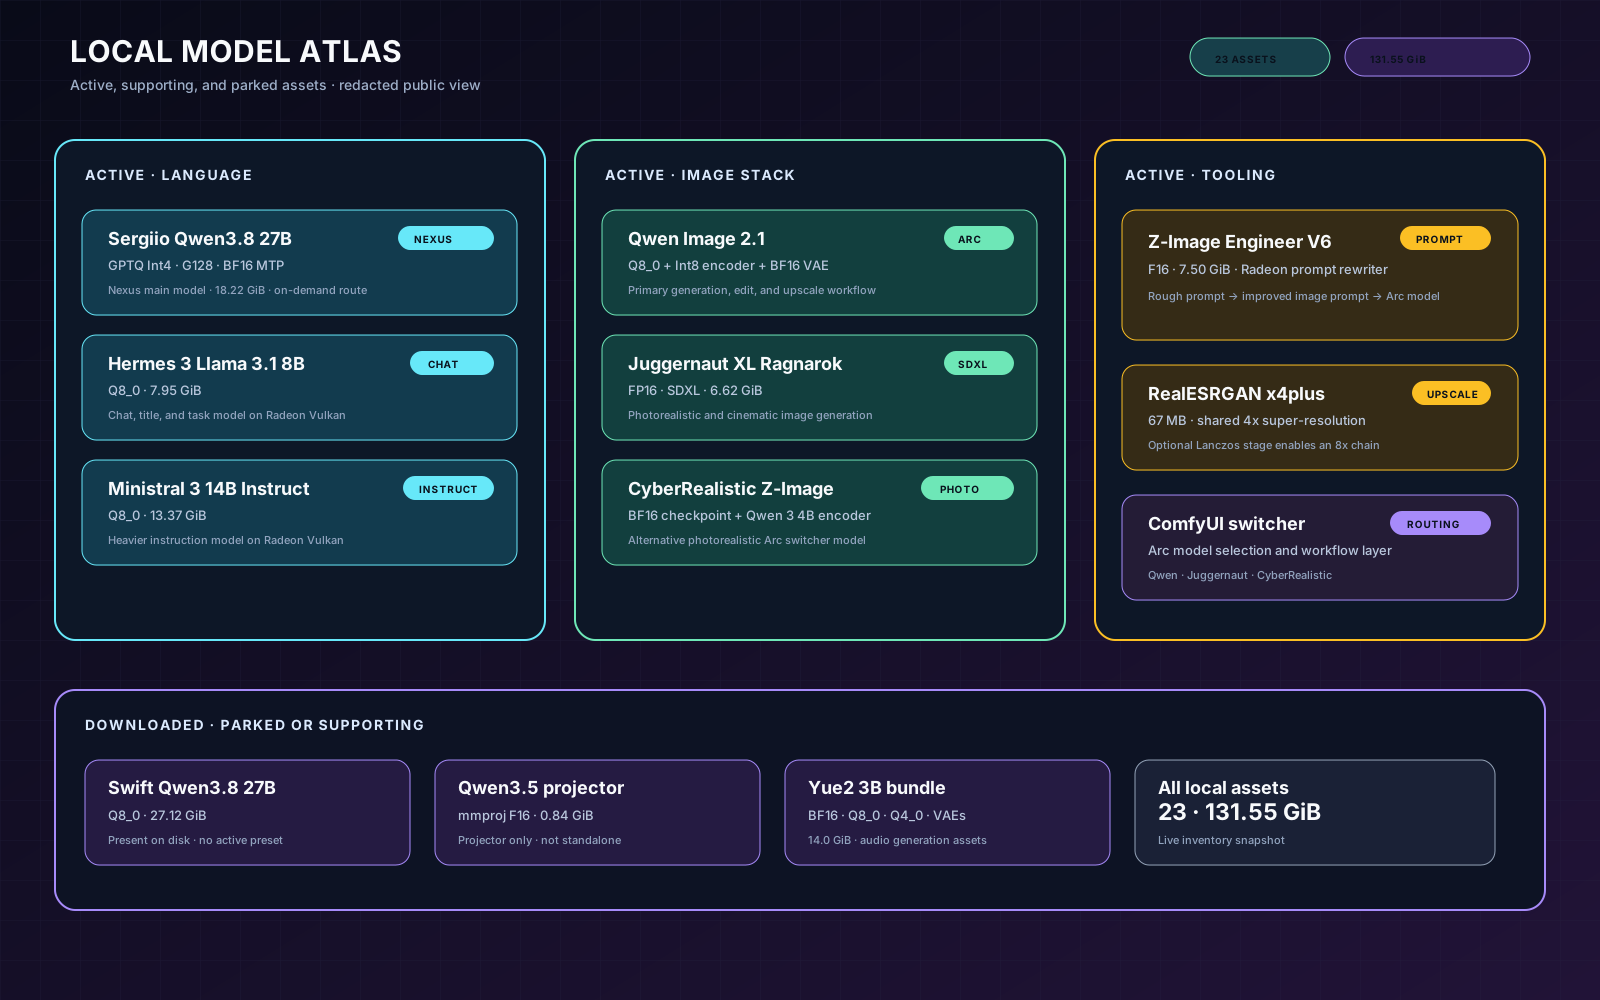
Architecture
web host / web host
  Caddy
    thesidequestlab.com
      WordPress container: WordPress-webcontainer
      MariaDB container:   WordPress-database

AI host / [internal AI host]
  Open WebUI, internal chat layer
       ├── main provider to internal main model route
       └── Radeon provider to internal Radeon model route

  main model route
       └── llama-swap / on-demand Qwen3.8 GPTQ MTP route

  Radeon route
       ├── Hermes 3 Llama 3.1 8B Q8_0
       ├── Ministral 3 14B Instruct Q8_0
       └── Z-Image Engineer V6 F16

  Intel Arc image stack
       ├── fixed Qwen Image ComfyUI service
       └── image-switcher ComfyUI
             ├── Qwen Image 2.1 Q8_0
             ├── Juggernaut XL Ragnarok FP16
             ├── CyberRealistic Z-Image Turbo Catalyst BF16
             └── RealESRGAN x4plus
Where vLLM fits
Current production path: the Nexus entry point is an internal OpenAI-compatible route fronted by llama-swap. When the Qwen route is idle, no vLLM container is visible. When a request loads the model, llama-swap starts the configured vLLM XPU backend on demand for the Sergiio Qwen3.8 GPTQ MTP model, and stops it again when it unloads.
Where llama.cpp fits: llama.cpp remains the active serving layer for the Radeon model route, including Hermes, Ministral, and the Z-Image prompt rewriter. A previous vLLM XPU A/B test is documented separately as historical context. This distinction keeps the documentation accurate without confusing an idle on-demand backend with an always-running process.
Active language models
1. Sergiio Qwen3.8 27B GPTQ Int4
This is the main model for Nexus and the heaviest general-purpose local language route. The model uses symmetric GPTQ Int4 with group size 128. Its MTP components are retained in BF16. It runs through the main route on the AI host and is loaded on demand, so it does not permanently occupy the Arc memory allocated to the image stack.
- Model ID:
SergiioB/Qwen3.8-27B-GPTQ-Int4-sym-G128-MTP-BF16 - Role: Nexus main model, general chat, reasoning, and vision-capable text interaction.
- Total shard size: 19,559,450,216 bytes, approximately 18.22 GiB.
- Route:
internal main model route, internal. - Download page: SergiioB Qwen3.8 27B GPTQ Int4 on Hugging Face.
The five local safetensors shards are:
| File | Bytes |
|---|---|
model-00001-of-00005.safetensors |
3,516,828,472 |
model-00002-of-00005.safetensors |
4,278,206,560 |
model-00003-of-00005.safetensors |
4,258,595,144 |
model-00004-of-00005.safetensors |
4,284,981,464 |
model-00005-of-00005.safetensors |
3,220,838,576 |
Local category: model-store/text/SergiioB/Qwen3.8-27B-GPTQ-Int4-sym-G128-MTP-BF16-r9d189a60/
2. Hermes 3 Llama 3.1 8B Q8_0
A compact general assistant for fast chats, Open WebUI tasks, and title generation. Its Q8_0 quantization keeps quality high while using substantially less memory than the 27B main route.
- File:
Hermes-3-Llama-3.1-8B.Q8_0.gguf - Size: 8,540,770,432 bytes, approximately 7.95 GiB.
- Role: Open WebUI chat, title model, and task model.
- Route: Radeon Vulkan on the
internal Radeon model route. - Download page: NousResearch Hermes 3 Llama 3.1 8B GGUF.
Local category: model-store/gguf/hermes-3-llama-3.1-8b/
3. Ministral 3 14B Instruct Q8_0
A larger instruction model for higher-quality chat and instruction tasks. It runs alongside Hermes in the Radeon router and is available in Open WebUI.
- File:
Ministral-3-14B-Instruct-2512-Q8_0.gguf - Size: 14,359,311,040 bytes, approximately 13.37 GiB.
- Role: Open WebUI model for heavier general instruction tasks.
- Route: Radeon Vulkan on the
internal Radeon model route. - Download page: Mistral AI Ministral 3 14B Instruct 2512 GGUF.
Local category: model-store/gguf/ministral-3-14b-instruct-2512/
Active image-generation stack
4. Qwen Image 2.1 Q8_0
The primary local image generator. It runs in ComfyUI on the Intel Arc Pro B70. The fixed service uses the Q8_0 diffusion model, the Int8 ConvRot text encoder, and the BF16 VAE. The workflow supports text-to-image, image editing, and the shared upscale chain.
- Diffusion model:
qwen-image-2.1-Q8_0.gguf, 7,591,557,792 bytes, Q8_0. - Text encoder:
qwen3vl_8b_int8_convrot.safetensors, 9,350,798,360 bytes, Int8. - VAE:
qwen_image_2.1_vae_bf16.safetensors, 675,509,688 bytes, BF16. - Bundle size: 17,617,865,840 bytes, approximately 16.41 GiB.
- Fixed service:
fixed Arc image service. - Public environment: helix.sgra.nexus/imagineer.
- Download page: abenzerps Qwen Image 2.1 GGUF.
- Exact Q8 file: qwen-image-2.1-Q8_0.gguf.
Local category: model-store/gguf/alternatives/qwen-image-2.1-gguf/
5. Juggernaut XL Ragnarok FP16
An SDXL checkpoint for photorealistic images, portraits, and cinematic scenes. It is not a Q4 or Q8 GGUF model, but an FP16 safetensors checkpoint. It is available through the Arc image switcher.
- File:
juggernautXL_ragnarok.safetensors - Size: 7,105,350,162 bytes, approximately 6.62 GiB.
- Role: photorealistic SDXL image generator.
- Local route: ComfyUI switcher on the
Arc image switcher. - Download page: Juggernaut XL Ragnarok on Civitai.
Local category: model-store/imagegen/juggernaut-xl/
6. CyberRealistic Z-Image Turbo Catalyst v2.0
A photorealistic image generator based on Z-Image Turbo. The local switcher uses a BF16 checkpoint, a Qwen 3 4B text encoder, and a BF16 VAE. The model card lists CreativeML OpenRAIL-M. Check the license terms before using output commercially.
- Checkpoint:
CyberRealistic_zit_catalyst_v2.0.safetensors, 12,566,044,072 bytes, BF16. - Text encoder:
qwen_3_4b.safetensors, 8,044,982,048 bytes. - VAE:
ae.safetensors, 335,304,388 bytes, BF16. - Bundle size: 20,946,330,508 bytes, approximately 19.51 GiB.
- Role: alternative photorealistic image generator in the Arc switcher.
- Download page: CyberRealistic Z-Image Turbo Catalyst on Hugging Face.
Local category: model-store/imagegen/cyberrealistic-zit/
7. RealESRGAN x4plus
The shared super-resolution component. It enlarges images four times while restoring and enhancing detail. The custom ImageGen workflow can optionally apply a further Lanczos step for a total 8x chain.
- File:
RealESRGAN_x4plus.pth - Size: 67,040,989 bytes.
- Role: shared 4x AI upscaler for the image workflows.
- Project: official Real-ESRGAN repository.
- Direct release download: RealESRGAN_x4plus.pth.
Local category: model-store/upscale/
Prompt rewriter on the Radeon
8. Z-Image Engineer V6 F16
This Qwen 3 4B-based prompt engineer runs on the Radeon. It is not intended as a normal chat model in Open WebUI. The custom ImageGen interface uses it as a local preprocessor:
- The user enters a short or rough prompt.
- Z-Image Engineer V6 turns it into a longer, technically improved image prompt.
- The final prompt is shown to the user and passed to the selected Arc image model.
- File:
Z-Image-Engineer-V6-F16.gguf - Size: 8,051,284,960 bytes, approximately 7.50 GiB.
- Precision: F16.
- Route: Radeon Vulkan on the
internal Radeon model route. - Download page: BennyDaBall Z-Image Engineer V6.
Local category: model-store/gguf/z-image-engineer-v6/
Downloaded but not actively exposed
9. Swift Qwen3.8 27B Q8_0
- File:
Swift-Qwen3.8-27B-Q8_0.gguf - Size: 29,116,389,280 bytes, approximately 27.12 GiB.
- Status: present on disk, but no active provider preset in the current route.
- Download page: UkisAI Swift Qwen3.8 27B GGUF.
Local category: model-store/gguf/swift-qwen3.8-27b/
10. Qwen3.5 35B A3B projector
- File:
mmproj-F16.gguf - Size: 899,283,648 bytes, approximately 0.84 GiB.
- Status: projector file only, not a complete standalone model in this location.
- Download page: Unsloth Qwen3.5 35B A3B GGUF.
Local category: model-store/gguf/alternatives/qwen3.5-35b-a3b/
11. Yue2 3B audio model bundle
Yue2 is not a chat or image model. It is a local text-to-audio and music-generation model bundle. There is currently no active Yue2 workflow in the image switcher or Open WebUI.
| File | Precision | Bytes |
|---|---|---|
yue2-3b-bf16.gguf |
BF16 | 7,261,475,392 |
yue2-3b-q8_0.gguf |
Q8_0 | 4,264,186,432 |
yue2-3b-q4_0.gguf |
Q4_0 | 2,665,632,320 |
yue2-vae-f16.gguf |
F16 VAE | 265,218,656 |
yue2-vae-f32.gguf |
F32 VAE | 530,537,760 |
Bundle size: 14,987,050,560 bytes, approximately 13.96 GiB.
Download page: audio-cpp Yue2 3B GGUF.
Local category: model-store/gguf/alternatives/yue2-3b-gguf/
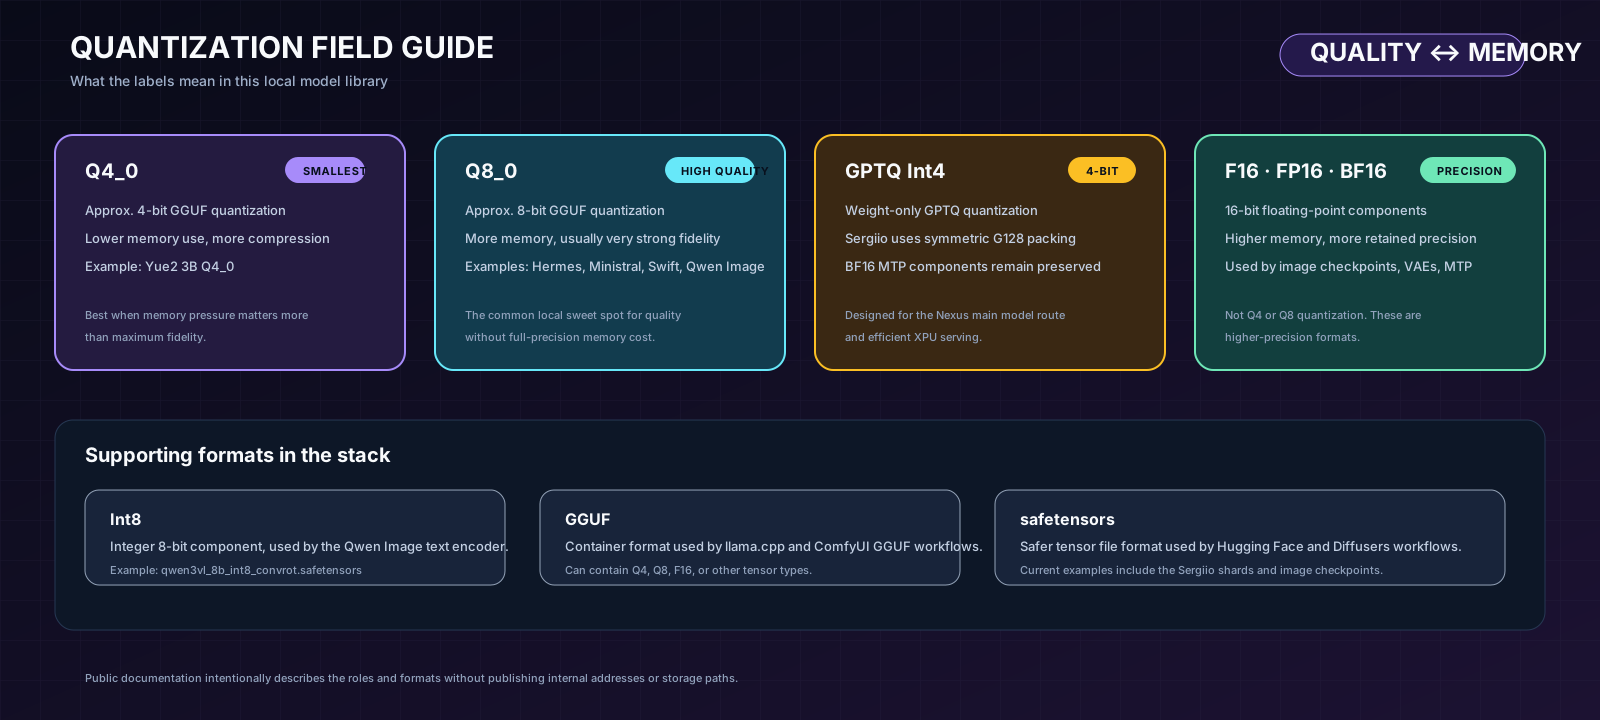
Quantization and file formats
- Q4_0: roughly 4-bit GGUF quantization. Smaller, but with more quality loss than Q8.
- Q8_0: roughly 8-bit GGUF quantization. Higher quality and higher memory use.
- GPTQ Int4: 4-bit GPTQ quantization. In the Sergiio model, the MTP draft components are intentionally retained in BF16.
- GGUF: a container format used locally with llama.cpp or specialized ComfyUI nodes.
- F16/FP16: 16-bit floating point. This is not traditional Q4 or Q8 quantization.
- BF16: 16-bit bfloat. Mainly used for higher-quality encoders, VAEs, and model components.
- Int8: 8-bit integer format, used in this setup for the Qwen Image text encoder.
- safetensors: a safer tensor file format for Hugging Face and Diffusers-style workflows.
What runs where?
| Layer | Hardware | Function | Live route |
|---|---|---|---|
| Nexus main model | AI host, on-demand XPU model route | Sergiio Qwen3.8 27B GPTQ Int4 MTP BF16 | internal main model route |
| Fast local chat | Radeon Vulkan | Hermes 3 Llama 3.1 8B Q8_0 | internal Radeon model route |
| Heavier instructions | Radeon Vulkan | Ministral 3 14B Q8_0 | internal Radeon model route |
| Prompt engineering | Radeon Vulkan | Z-Image Engineer V6 F16 | internal Radeon model route |
| Qwen Image | Intel Arc Pro B70 | Qwen Image 2.1 Q8 plus Int8 encoder plus BF16 VAE | fixed Arc image service |
| Image switcher | Intel Arc Pro B70 | Qwen Image, Juggernaut XL, CyberRealistic | Arc image switcher |
| Upscaling | Intel Arc Pro B70 | RealESRGAN x4plus, plus optional Lanczos step | part of ImageGen |
WordPress and web-host layer
This site runs on the web host behind Caddy. Caddy publishes thesidequestlab.com and proxies requests to the WordPress container. WordPress uses MariaDB as a separate container. The WordPress web binding is local-only and is not published directly to the public internet.
- WordPress container:
WordPress-webcontainer, imagewordpress:php8.2-apache. - Database container:
WordPress-database, MariaDB. - Caddy: reverse proxy and TLS termination.
- Local WordPress binding: local-only and not directly publicly reachable.
- Public canonical URL: https://thesidequestlab.com/.
What is intentionally not included on this page
- No passwords, API keys, bearer tokens, or database passwords.
- No SSH private keys or session cookies.
- No raw environment files.
- No internal configuration rules that could reconstruct credentials.
- No claim that a public Open WebUI hostname works while its TLS route is not healthy.
Sources and download pages
The model references were checked against model cards or official project pages. Local presence, file sizes, and active routes were checked live on the AI host on 21 September 2026.
- SergiioB Qwen3.8 27B GPTQ
- NousResearch Hermes 3 GGUF
- Mistral AI Ministral 3 GGUF
- Qwen Image 2.1 GGUF
- Juggernaut XL Ragnarok
- CyberRealistic Z-Image Turbo Catalyst
- BennyDaBall Z-Image Engineer V6
- Swift Qwen3.8 27B GGUF
- Qwen3.5 35B A3B GGUF
- Yue2 3B GGUF
- Real-ESRGAN
Maintenance note: this article describes a live snapshot. Recheck the page after model changes, new routes, or security changes. Sirius will not place credentials or secret configuration values in this documentation.